I'm Begging You to Understand Your Environment and Policy
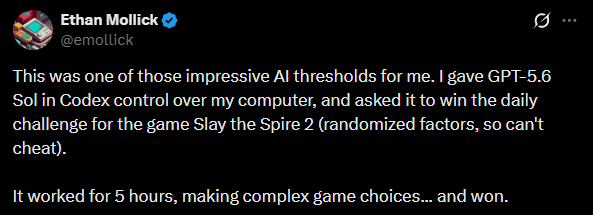
A short post based on something I read yesterday. As a long time Slay the Spire 1 player, I’m very happy to see the attention that Slay the Spire 2 has received. As a result, it’s also brought some renewed attention on Slay the Spire as a benchmark for agents, especially LLMs: Claude Fable 5, GPT-5.6 Sol daily run, GPT-5.6 Sol streaming (thank god, at least this one comes from people who are familiar with the environment). While you may know that I am less optimistic about LLM progress (topic for another post, it’s nuanced), I don’t mean to make any claims about that here. I am simply asking people to be more reasonable about claims they make when analyzing benchmarks, which has been a problem for a very long time even before LLMs. If you just want to see my comments about Slay the Spire and the given tweet, skip to the bottom.
Understanding your environment and policy is really good
While games as RL environments are useful for many reasons (perfect and fast simulation, not artificially constructed for a benchmark, cultural interest, etc.), I think one of the most powerful properties of games is that we understand many games very thoroughly. Contrast with continuous control/robotics, where it’s the rule rather than the exception for environments to have completely opaque dynamics to us (https://www.alexirpan.com/2018/02/14/rl-hard.html, vaulting in https://wang-kevin3290.github.io/scaling-crl/, https://openai.com/index/emergent-tool-use/, to name just a few). In the best case with human teleoperation, we understand only a few suboptimal policies that are “good enough.”
And understanding an environment thoroughly (including how to perform well) is extremely valuable. You get so few bits of information looking at metrics alone, but by understanding the environment you can analyze the trajectories and get significantly richer information. You may be much more familiar with the version of this claim for supervised learning, where understanding your dataset thoroughly is important (https://karpathy.github.io/2019/04/25/recipe/).
- When a model performs poorly, you can see what kinds of states it tends to mess up in, and how it thinks about the value of certain actions compared to what the correct values should be. It’s much easier to make generalizations about the class of problems this environment represents, what the problems are, and how to address them.
- When a model performs well, you can see to what extent it actually understands various aspects of the task, or whether it has found some kind of way to “cheese” the problem and still has significant gaps in most aspects of its performance.
Without understanding an environment and analyzing policy trajectories, it’s extremely difficult to make credible and robust claims about what kind of knowledge a given agent actually has about a task or how well it might generalize. But I consistently see such claims by people who have spent almost no time actually analyzing what the policy is doing and have little understanding of the task. I think more people should be trying environments in a similar way to a twitter thread I made about this.
Methods frequently break in ways that are relatively predictable given this analysis (because we can find significant signs of brittleness). But without this analysis it’s easy to misunderstand what the method is actually good at, such that it “unintuitively” fails in supposedly similar environments or even more damningly (but likely very common, e.g.https://arxiv.org/abs/2410.08870) when we modify the environment or co-agents in ways we think should be irrelevant. Perhaps due to being unwilling to expose their method’s brittleness or “cheesing,” people seem entirely uninterested in doing this analysis, or doing it in an even-handed way. Even in rare cases when this analysis is done, it is almost always a cherry-picked analysis of certain cute phenomena where the model is good. But at this point I’ll take anything.
How did everyone manage to miss this, isn’t Slay the Spire popular now
Now for a case study where people are both failing to analyze the policy in any capacity, and severely misunderstanding what they consider to be a mostly irrelevant change to the environment. I know this is the machine-cult worshipping side of ML twitter, but even in spaces where people are careful about having good discourse, I tend to see similar things. 100 comments, 1/3 asking questions (the rest just glazing it, frequently with high confidence and clearly no knowledge, especially blindly applying “task length” to a task that has very little relation between knowledge and time spent), and out of these there are like 2 questions asking about the policy and the task (the fact that it was a daily). A decent number of people are at least somewhat knowledgeable about Spire, so it’s a shame to see no one knowledgeable in the comments weighing in on it at all. Instead we speculate wildly, motivated by the OP’s misrepresentation of the task. People are also ignoring the heavy variance in the game, though I suspect this is just inexperience from people who do seem to have played a bit of Spire in the comments. One win (and survivorship bias) does not mean much, neither does one loss. To get any signal, you have either have to look at the decisions made, or get around 30-100 games worth of samples. When analyzed, the policy is poor; low elite count especially after book of five rings, excessive fires (upgrades are almost useless with the huge deck, but elites and hallways are good for your deck strength), punch dagger purchase with huge deck, etc. and this is without seeing fight choices, card picks, and all the other stuff we can’t see here. Of course, the LLM is not completely clueless, but my point is that failing to make quick and simple observations about the policy is just a massive and avoidable mistake in how well you actually understand what you are looking at.
And here is the real kicker, which no one is commenting on for some odd reason, while pretending the result is so great. In this daily run, you start with Hoarder (3x cards to deck) and that you get to draft your initial 10 cards, along with a curse at the start of each act. It’s really the drafting 10 initial cards that is insane. In the given seed you even get book of five rings so you’re just healing for an extra 60 every act. If you play chess, this is like playing with all your pawns turned into knights, it’s absurd. But then the LLM is winning by the skin of its teeth… what? This would be marginally more defensible if some baseline was given or some remark was made about it being easy from either the author or the readers, or we could analyze the picks or the card plays or anything, but instead all we see is a comment from the author about how the daily challenge avoids cheating, rather than about how it makes the run much easier. Be better.
So, I’m begging you. Please understand the environment and policy before you make or trust claims about the difficulty of an environment and the quality of a method. This case (OP + reader reception) is not at all unusual in how misleading it is.